ZAI Language
GLM-5.3-Flash (FP4)
Natively multimodal coding model with 1M context at flash-tier pricing.
About
GLM-5.3-Flash-FP4 is GLM-5.3-Flash served from an MXFP4-quantized checkpoint. GLM-5.3-Flash is the first natively multimodal model in Z.ai's GLM-5 series, a 320B-parameter Mixture-of-Experts design that activates 18B per token, pairing linear attention for local context with sparse attention and a lightweight indexer for global retrieval across its 1M-token window. The 4-bit expert weights cut serving cost while staying close to the FP8 model on agentic coding benchmarks.
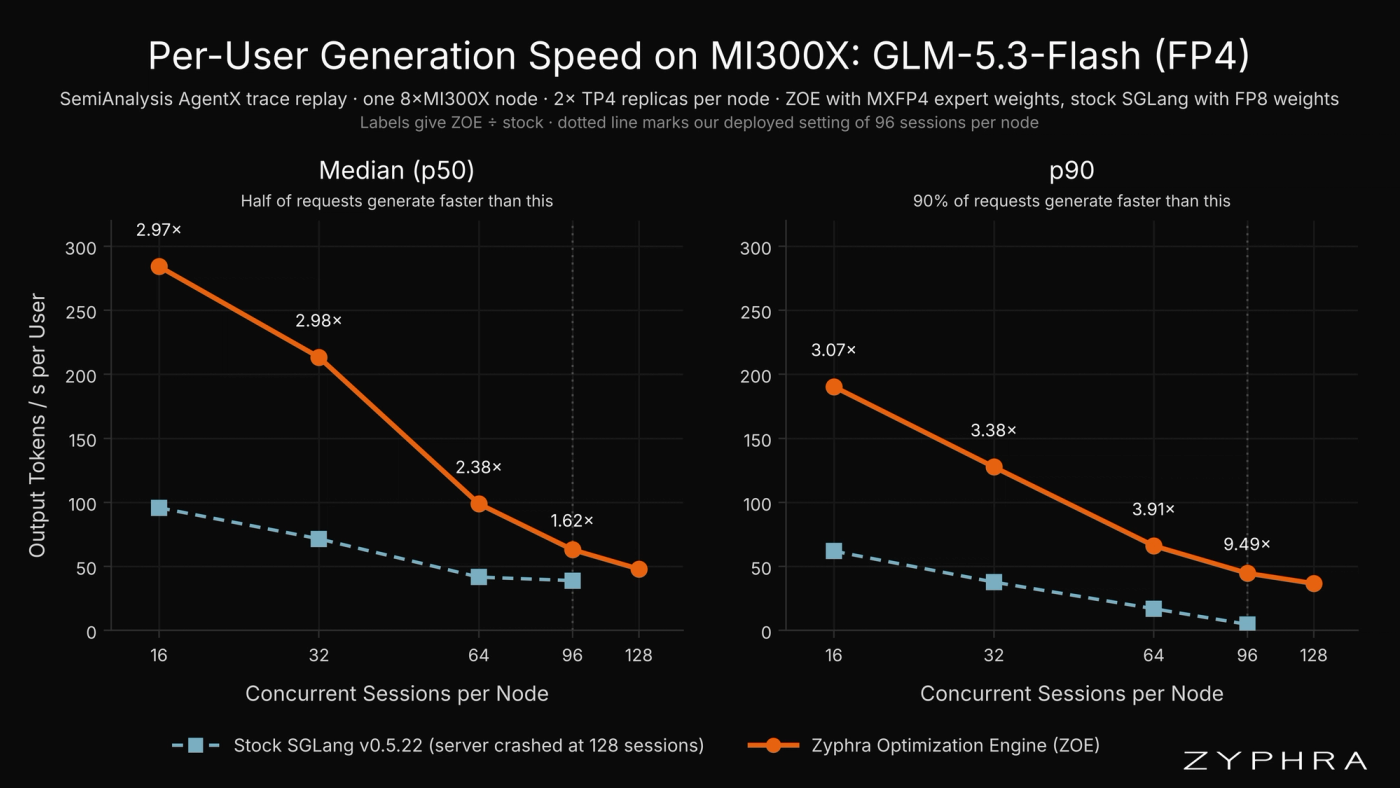
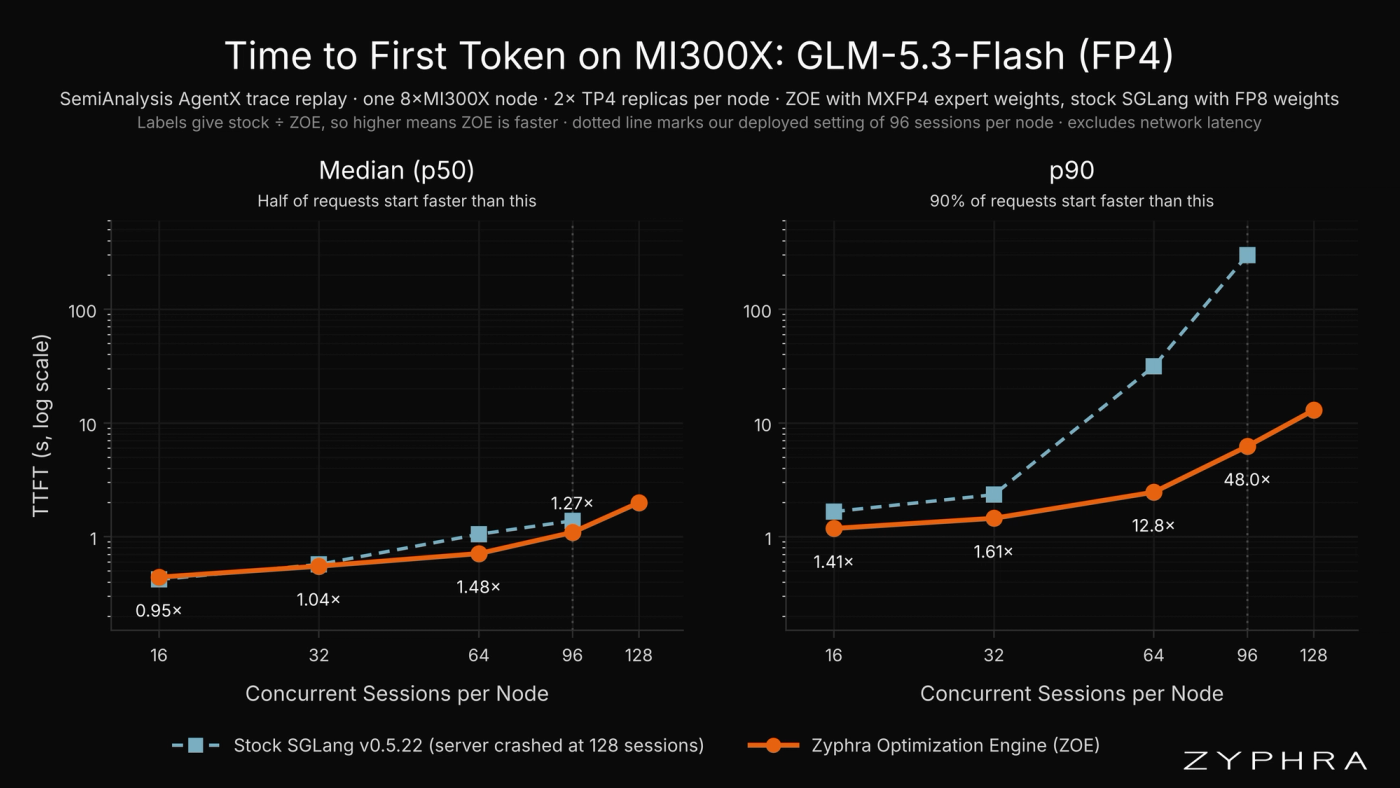
Performance Benchmarks on Zyphra Inference with Zyphra Optimization Engine
We compared ZOE with stock SGLang (v0.5.22) on one 8xMI300X node using SemiAnalysis AgentX (a replay of multi-turn coding agent sessions).
API usage
import os
from openai import OpenAI

client = OpenAI(
    api_key=os.getenv("ZYPHRA_API_KEY"),
    base_url="https://api.zyphracloud.com/api/v1",
)

response = client.chat.completions.create(
    model="zai-org/GLM-5.3-Flash-FP4",
    messages=[{"role": "user", "content": "Hello!"}],
)

print(response.choices[0].message.content)
import OpenAI from "openai";
const client = new OpenAI({
apiKey: process.env.ZYPHRA_API_KEY,
baseURL: "https://api.zyphracloud.com/api/v1",
});
const response = await client.chat.completions.create({
model: "zai-org/GLM-5.3-Flash-FP4",
messages: [{ role: "user", content: "Hello!" }],
});
console.log(response.choices[0].message.content);curl https://api.zyphracloud.com/api/v1/chat/completions \
-H "Authorization: Bearer $ZYPHRA_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"model": "zai-org/GLM-5.3-Flash-FP4",
"messages": [{"role": "user", "content": "Hello!"}]
}'More models
ZAI LanguageGLM 5.3Frontier open coding model with 1M context and emergent cyber defense capability.Read the releaseZAI LanguageGLM-5.3-FlashNatively multimodal coding model with 1M context at flash-tier pricing.Open the modelMoonshot AI LanguageKimi-K3Open frontier multimodal MoE for long-horizon coding and agents with a 1M-token context windowRead the release